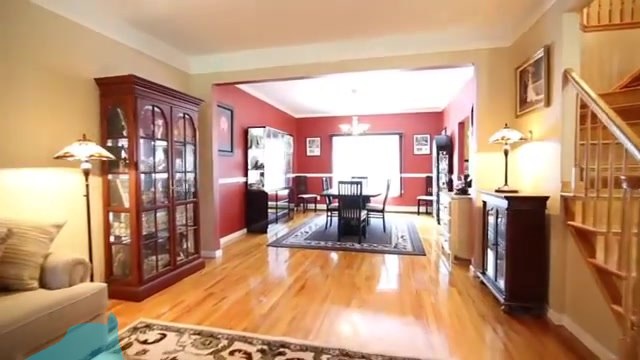
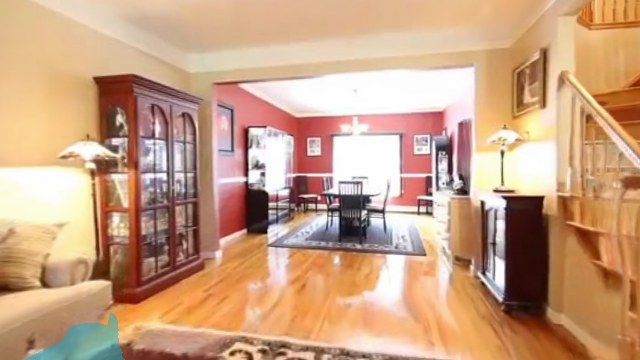
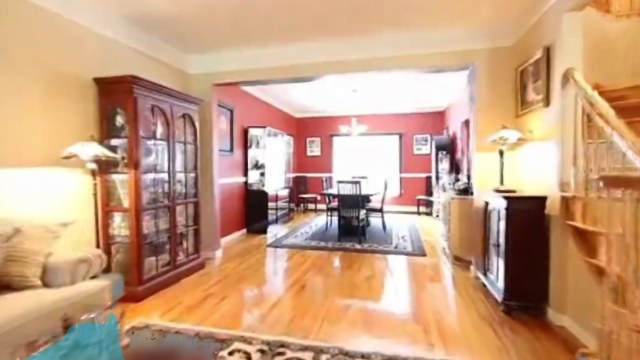
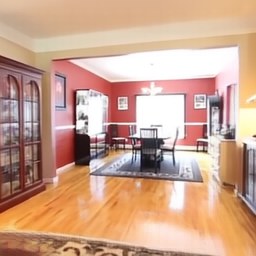
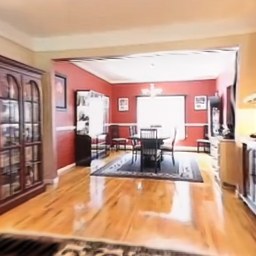
Same Flash3D reconstruction, same target view.
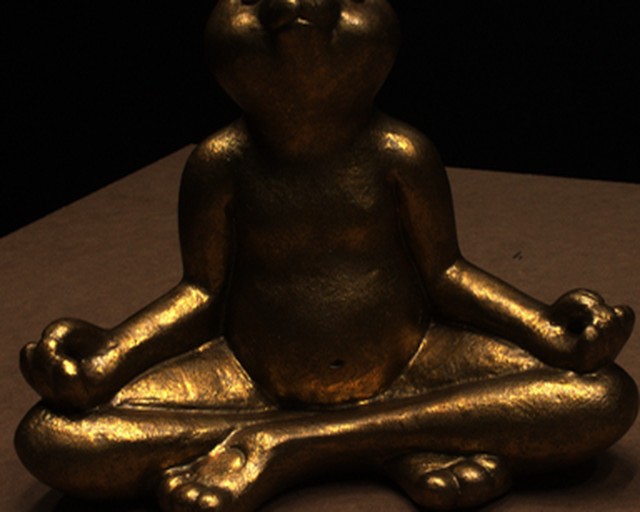
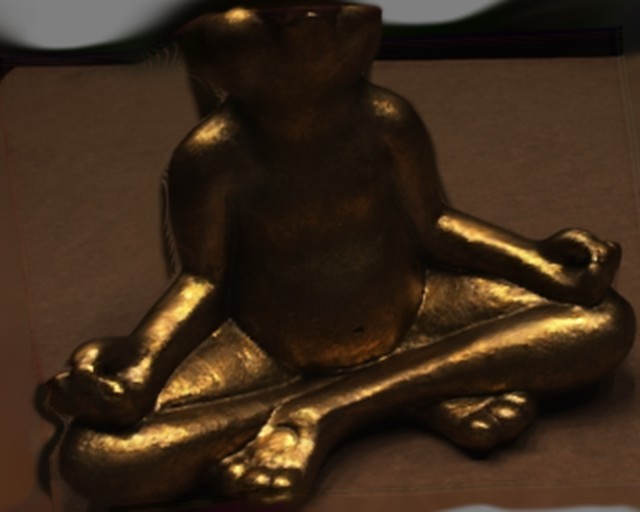
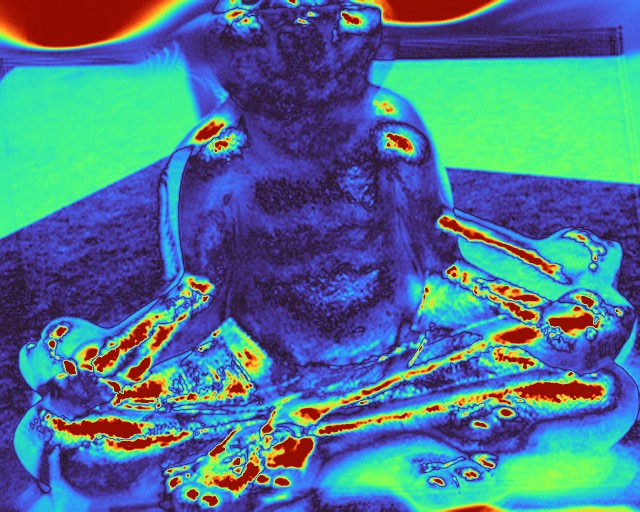
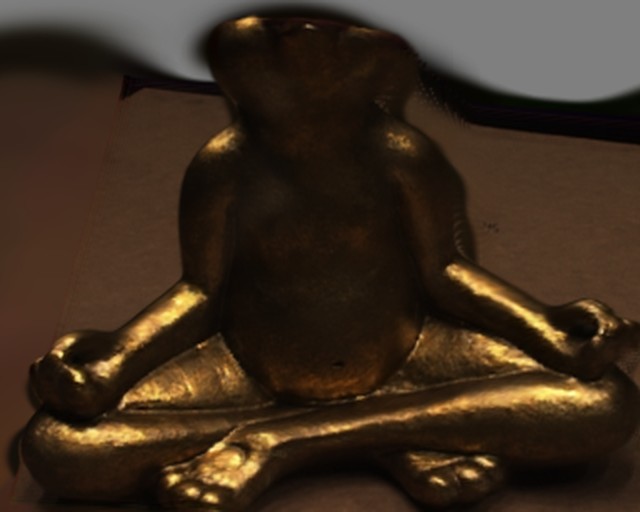
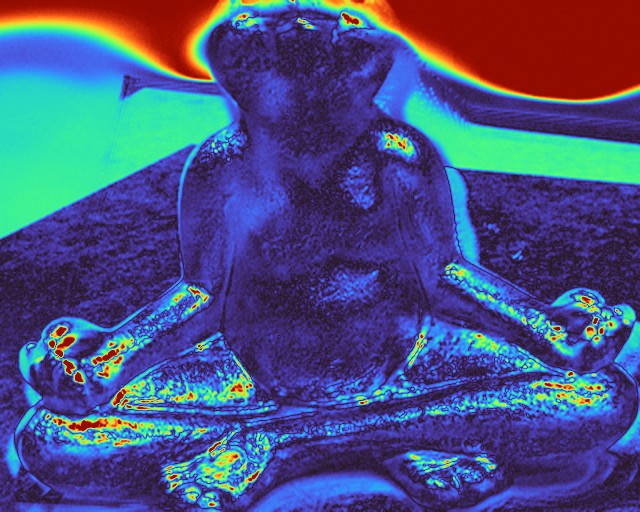
LowHigh error
WACV 2027
1University of British Columbia2Google
TL;DRA single image fixes a scene only up to scale, and photometric optimization often fails to recover the resulting misalignment.We propose a new evaluation protocol that aligns renders to the ground truth with traditional image matching and scores only co-visible pixels.
While single-view novel view synthesis methods have been dramatically enhanced recently, how to quantify their performance has yet to be standardized. In this work, we demonstrate that an important factor lies in how each method’s own reference frame is aligned with the so-called ground-truth pose. Existing methods often rely on test-time optimization of target poses for this alignment, which inherently is ill-posed due to the complexity of the optimization landscape of camera poses vs render accuracy, leading to methods being evaluated at an arbitrary local optimum. Some recognize this limitation and thus rely on 3D reconstructions of entire scenes using training and test views to align poses, which may be infeasible.
In this work, instead, we propose to use traditional 2D-to-2D and 2D-to-3D image matching techniques to align 3D reconstructions. We also evaluate only within co-visible regions, between different views, which is the only place where a ‘correct’ ground truth can be defined. Our evaluations show that with proper coordinate alignment, novel-view synthesis methods that use explicit 3D Gaussians achieve the state of the art, despite being previously reported in the literature to be outperformed by pure image-based 2D methods. We further provide a simple baseline that directly utilizes an off-the-shelf video generator and a feed-forward geometry estimator. Our simple baseline is already comparable to state-of-the-art methods specifically trained for novel-view synthesis, without any task-specific training.
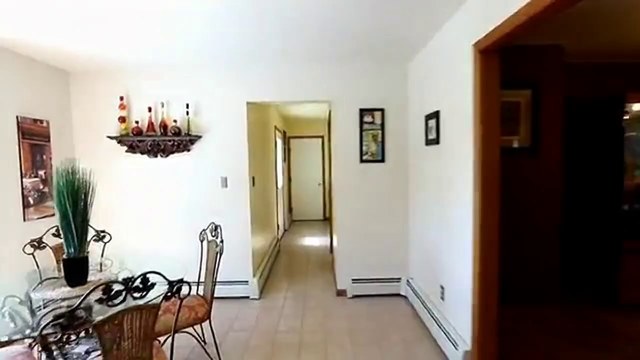
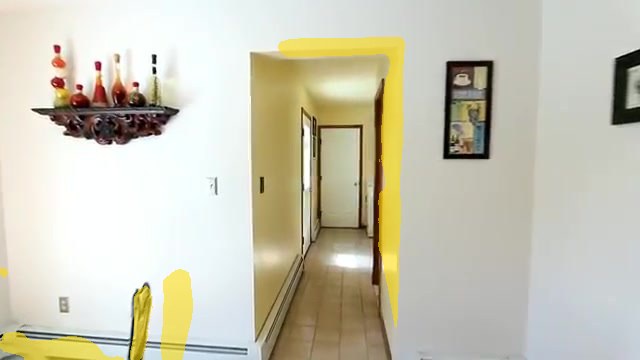
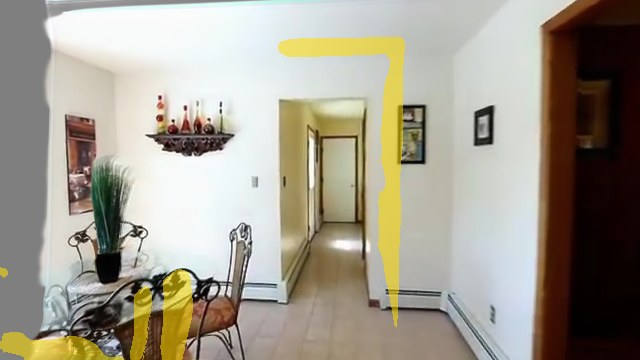
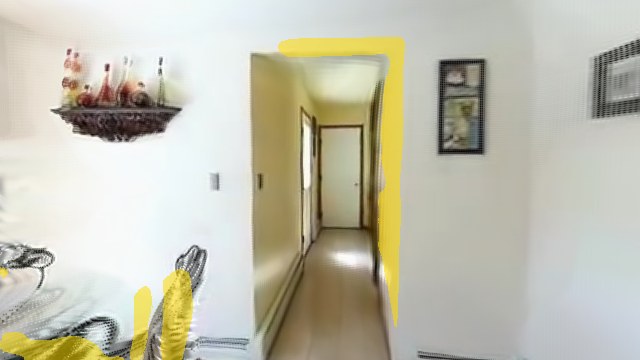
We render the reconstruction at the pose the benchmark gives for the target view, then match keypoints between the render and the target view in 2D.
A toy scene, ray-traced in your browser. Matches are simulated from the scene geometry, with noise and outliers; P3P, RANSAC and the Levenberg–Marquardt refinement run for real. The numbers in this demo are not results from the paper.
| Method | RE10K (SV) | RE10K (VC) | DL3DV-10K (SV) | DTU | T&T (VC) | Avg PSNR | Avg SSIM | Avg LPIPS |
|---|---|---|---|---|---|---|---|---|
| Test-time optimization only | ||||||||
| Ours | 18.85 | 16.03 | 12.74 | 11.83 | 14.30 | 14.75 | 0.514 | 0.557 |
| Flash3D | 14.52 | 14.75 | 11.71 | 11.12 | 13.75 | 13.17 | 0.473 | 0.590 |
| DepthSplat | 16.66 | 16.45 | 12.77 | 10.67 | 13.59 | 14.03 | 0.466 | 0.526 |
| Lyra | 17.50 | 16.20 | 12.34 | 12.68 | 15.38 | 14.82 | 0.504 | 0.504 |
| AnySplat | 19.40 | 19.03 | 13.54 | 12.82 | 14.81 | 15.92 | 0.535 | 0.470 |
| SHARP | 20.77 | 19.45 | 13.57 | 12.83 | 15.55 | 16.43 | 0.564 | 0.419 |
| Our evaluation protocol | ||||||||
| Ours | 22.26 | 21.30 | 14.13 | 17.47 | 16.80 | 18.39 | 0.605 | 0.389 |
| Flash3D | 22.04 | 20.77 | 13.51 | 17.06 | 17.68 | 18.21 | 0.594 | 0.416 |
| DepthSplat | 17.82 | 17.64 | 13.20 | 13.51 | 14.39 | 15.31 | 0.494 | 0.454 |
| Lyra | 21.66 | 21.02 | 14.68 | 17.98 | 19.27 | 18.92 | 0.624 | 0.362 |
| AnySplat | 20.72 | 19.80 | 14.24 | 17.18 | 16.73 | 17.74 | 0.547 | 0.394 |
| SHARP | 21.29 | 20.03 | 14.41 | 16.16 | 16.84 | 17.74 | 0.575 | 0.353 |
| GT pose | ||||||||
| ViewCrafter | 14.34 | 16.70 | 13.32 | 13.85 | 16.42 | 14.93 | 0.508 | 0.418 |
Bold best, underlined second, per group.
| Method | RE10K (SV) | RE10K (VC) | DL3DV-10K (SV) | DTU | T&T (VC) | Avg PSNR | Avg SSIM | Avg LPIPS |
|---|---|---|---|---|---|---|---|---|
| Test-time optimization only | ||||||||
| Ours | 20.73 | 16.08 | 13.04 | 11.82 | 14.09 | 15.15 | 0.449 | 0.527 |
| LVSM | 19.76 | 19.54 | 13.37 | 12.58 | 16.16 | 16.28 | 0.489 | 0.445 |
| MVSplat | 15.51 | 14.54 | 11.91 | 10.34 | 12.41 | 12.94 | 0.395 | 0.534 |
| DepthSplat | 17.47 | 16.10 | 12.39 | 12.01 | 13.49 | 14.29 | 0.455 | 0.488 |
| NoPoSplat | 13.42 | 12.29 | 11.31 | 9.41 | 11.51 | 11.59 | 0.348 | 0.657 |
| PF3plat | 18.25 | 15.91 | 10.59 | 12.82 | 12.95 | 14.10 | 0.426 | 0.444 |
| Our evaluation protocol | ||||||||
| Ours | 22.29 | 21.40 | 14.73 | 17.49 | 17.40 | 18.66 | 0.587 | 0.331 |
| LVSM | 20.17 | 20.72 | 13.74 | 15.45 | 17.36 | 17.49 | 0.534 | 0.363 |
| MVSplat | 16.49 | 15.71 | 13.12 | 13.23 | 13.75 | 14.46 | 0.513 | 0.386 |
| DepthSplat | 17.95 | 16.81 | 12.53 | 14.64 | 14.15 | 15.22 | 0.503 | 0.405 |
| NoPoSplat | 18.31 | 17.25 | 12.81 | 13.16 | 14.02 | 15.11 | 0.483 | 0.423 |
| PF3plat | 18.41 | 15.83 | 11.50 | 16.51 | 13.61 | 15.17 | 0.503 | 0.377 |
Flash3D and ViewCrafter have no 256×256 output.